Optimize ExecuTorch fallback with CMSIS-NN on Cortex-M
Introduction
Understand and prepare the environment
Lower a model to the Cortex-M backend
Add Ethos-U delegation and CPU fallback
Inspect the generated CMSIS Pack selection
Understand the reusable CMSIS project
Build and run the mixed application
Next Steps
Optimize ExecuTorch fallback with CMSIS-NN on Cortex-M
Deploy across Cortex-M and Ethos-U NPU
After seeing what running the model exclusively on Cortex-M looks like, set up deployment across Cortex-M and the Ethos-U NPU.
Re-use the same exporter script as earlier, this time creating a fallback. The exporter uses EthosUPartitioner to
create an Ethos-U55 delegate region, represented by executorch_call_delegate.
It then applies CortexMPassManager to operations left outside that
delegate. The exporter lowers its supported convolution to a registered Cortex-M operator
implemented by CMSIS-NN.
See how the export script creates a fallback
For supported neural-network operations, the expected order is Ethos-U NPU, then CMSIS-NN on the Cortex-M CPU, then a portable CPU kernel. This keeps as much work as possible on the NPU. It gives unsupported quantized work an optimized CPU route before using a general implementation.
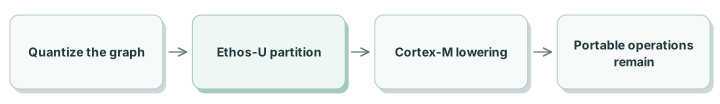 ExecuTorch partitioning and lowering order
The ordering matters. If Cortex-M lowering runs first, it can rewrite a convolution that should be offered to the NPU.
The exporter first creates an Ethos-U55 compile specification and configures the target-specific quantizer:
compile_spec = EthosUCompileSpec(target=args.target)
quantizer = EthosUQuantizer(compile_spec)
quantizer.set_global(
    get_symmetric_quantization_config(is_per_channel=True)
)
After quantization, EthosUPartitioner identifies supported regions and lowers
them into an Ethos-U delegate:
edge_program_manager = to_edge_transform_and_lower(
    quantized_exported_program,
    partitioner=[EthosUPartitioner(compile_spec)],
    compile_config=EdgeCompileConfig(_check_ir_validity=False),
)
The exporter then applies Cortex-M lowering to the operations that remain outside the delegate:
edge_program_manager._edge_programs["forward"] = CortexMPassManager(
    edge_program_manager.exported_program(), use_explicit_layout=True
).transform()
This run uses the ethos-u55-128 target to create the predictable fallback
described earlier.
Export the model for Cortex-M and Ethos-U
Run the export script in mixed Cortex-M and Ethos-U mode:
python export_cortex_m_fallback.py \
  --mode ethos-u-fallback \
  --target ethos-u55-128 \
  --model-file model/model.py \
  --output-dir artifacts
python .\export_cortex_m_fallback.py `
  --mode ethos-u-fallback `
  --target ethos-u55-128 `
  --model-file model/model.py `
  --output-dir artifacts
The export script prints a summary of the graph before and after Cortex-M lowering:
        Relevant targets before Cortex-M lowering:
aten.convolution.default: 1
aten.topk.default: 1
executorch_call_delegate: 1

Relevant targets after Cortex-M lowering:
aten.topk.default: 1
cortex_m.dequantize_per_tensor.default: 2
cortex_m.quantize_per_tensor.default: 2
cortex_m.quantized_conv2d_nhwc.default: 1
cortex_m.transpose.default: 2
executorch_call_delegate: 1
The final graph contains all three execution paths:
executorch_call_delegatecontains the stride-1 convolution that’s accepted by Ethos-U55.cortex_m.quantized_conv2d_nhwcis the stride-4 convolution that’s rejected by Ethos-U55 and lowered to CMSIS-NN.aten.topkremains a portable FP32 operation.
Use the CMSIS-Executorch project workflow
The CMSIS-Executorch project workflow uses create_ai_layer.py to complete the following tasks:
- Model export
.ptegeneration- Selection of source components required to run the model
So far, you’ve used a separate script for these tasks. By using create_ai_layer.py instead, you’ll benefit from the rest of the setup.
The pre-existing create_ai_layer.py doesn’t include CMSIS-NN lowering. You’ll add this through a targeted patch that makes four key changes:
- It adds
ARM::CMSIS-NN@8.0.0to the Pack list of the solution. - It applies Cortex-M lowering after Ethos-U partitioning.
- It maps explicit-layout names such as
quantized_conv2d_nhwcto their Pack component names. - It selects the CMSIS-NN library when the exported program contains a CMSIS-NN-backed Cortex-M operator.
Check and apply the patch, then inspect its small project diff:
git apply --check enable_cortex_m_fallback.patch
git apply enable_cortex_m_fallback.patch
git --no-pager diff -- cmsis-executorch-u55.csolution.yml create_ai_layer.py
No board, runner, or linker changes are needed.
Generate the target description
Resolve the declared Packs and active target:
cbuild setup cmsis-executorch-u55.csolution.yml --active SSE-300-U55 --packs
This command installs missing packs through the public Pack index and writes three useful descriptions:
cmsis-executorch-u55.cbuild-pack.ymllocks the resolved Pack versions.cmsis-executorch-u55.cbuild-mlops.ymldescribes the Cortex-M55, Ethos-U55, Vela settings, and destination AI layer.cmsis-executorch-u55.cbuild-idx.ymlindexes the resolved build context.
Generate the AI layer
Use the MLOps description to export the model and write its CMSIS AI layer:
python create_ai_layer.py cmsis-executorch-u55.cbuild-mlops.yml
python .\create_ai_layer.py .\cmsis-executorch-u55.cbuild-mlops.yml
The output is similar to:
        [ai_layer] 7608 byte program, operators: ['Cortex-M dequantize_per_tensor', 'Cortex-M quantize_per_tensor', 'Cortex-M quantized_conv2d', 'Cortex-M transpose', 'Portable topk']
[ai_layer] wrote .../ai_layer/ai_layer.clayer.yml
The generator writes the final model.pte and converts the .pte file to C data for the
firmware. It then records the runtime and operator components that are needed to run the file.
What you’ve accomplished and what’s next
You’ve produced a model-specific AI layer with one Ethos-U55 delegate, one CMSIS-NN-backed fallback convolution, and one portable operation. The split is decided ahead of time and stored in the ExecuTorch program.
Next, you’ll inspect how the two published source Packs supply the code behind those graph targets.