View the DistilBERT benchmark results
Open the benchmark dashboard
In addition to the GPT-2 results, the results directory should now contain three DistilBERT files:
distilbert_pytorch.jsondistilbert_portable.jsondistilbert_xnnpack.json
The same dashboard can display the GPT-2 and DistilBERT results together. If it is still running from the GPT-2 section, refresh the browser. Otherwise, restart it from the Raspberry Pi:
course_support/serve_results.py \
  --results ~/executorch_on_arm/module-1-transformer-inference-with-xnnpack/results \
  --host 127.0.0.1 \
  --port 8080
Open the same local URL on your development machine:
http://localhost:8080
Example DistilBERT results are provided below, and yours will likely show a similar pattern, though are unlikely to be identical:
| Runtime | Warmups | Runs | Mean | Median | Min | Max |
|---|---|---|---|---|---|---|
| PyTorch eager | 2 | 20 | 190.75 ms | 190.59 ms | 188.59 ms | 193.06 ms |
| ExecuTorch with portable kernels | 1 | 1 | 20,699.95 ms | 20,699.95 ms | 20,699.95 ms | 20,699.95 ms |
| ExecuTorch with XNNPACK | 2 | 20 | 80.94 ms | 80.82 ms | 80.43 ms | 82.45 ms |
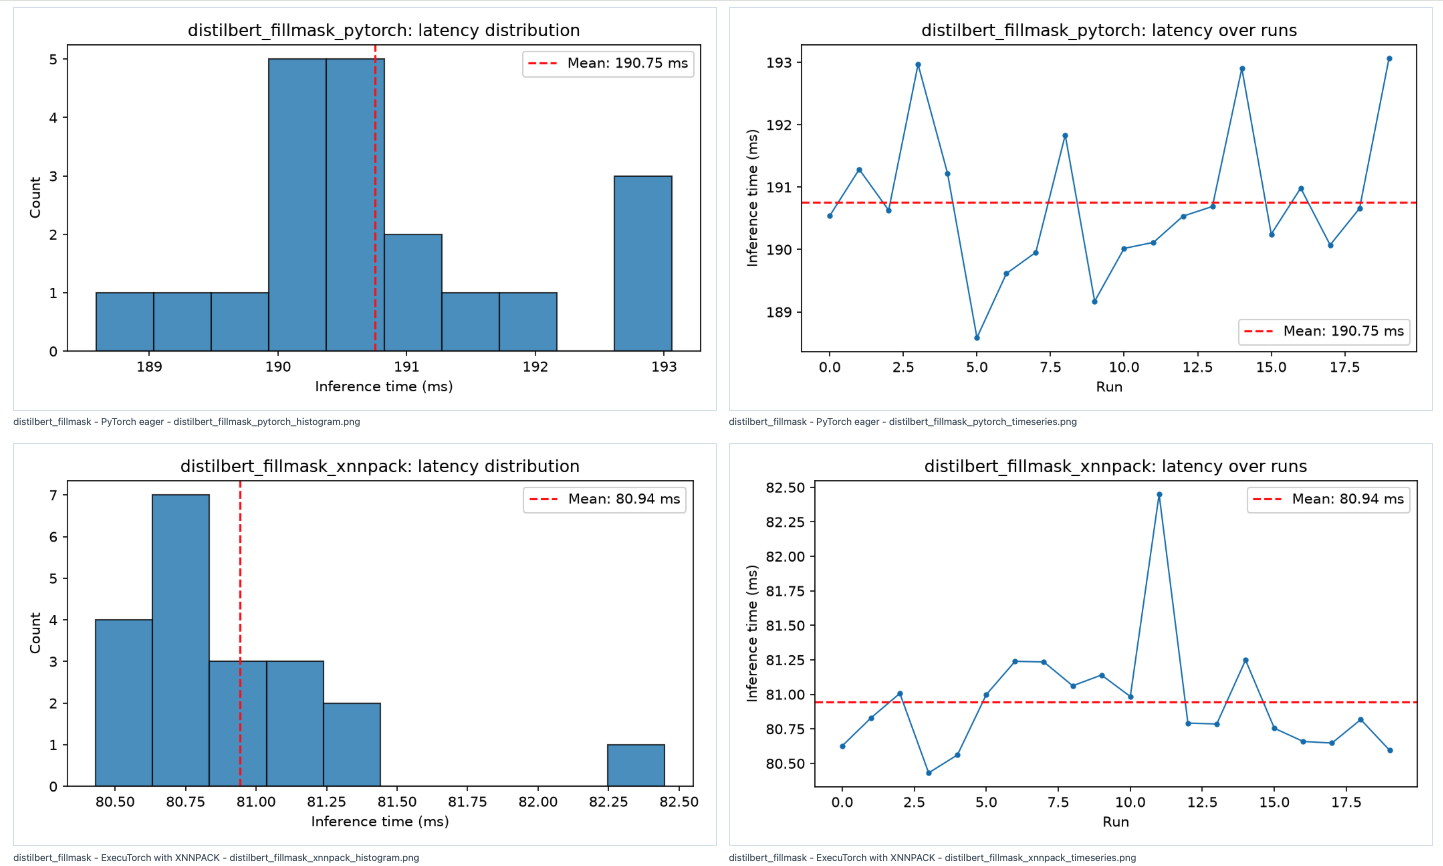
In the example data, you will see the same pattern repeated from the GPT-2 tests.
XNNPACK reduced mean latency from 190.75 ms for PyTorch eager execution, to 80.94 ms, a speedup of approximately 2.4×. The single run of the portable kernel artifact took around 20.7 seconds.
Course complete
Nice work
You completed Optimize and deploy AI inference with ExecuTorch on Arm.