Run the GPT-2 text-generation demo
The benchmark measured one fixed forward pass. The GPT-2 demo shows how the same ExecuTorch with XNNPACK .pte artifact can be integrated into a small application loop.
Run the following on the Raspberry Pi:
module-1-transformer-inference-with-xnnpack/scripts/pi/serve_gpt2_generation.py \
  --spec ~/executorch_on_arm/module-1-transformer-inference-with-xnnpack/artifacts/gpt2/model_spec.json \
  --pte ~/executorch_on_arm/module-1-transformer-inference-with-xnnpack/artifacts/gpt2/gpt2_xnnpack.pte \
  --host 127.0.0.1 \
  --port 8090
Then open:
http://localhost:8090
Try out the application by entering a prompt and generating text. The timing panel reports the end-to-end request time, first-token latency, average decode-step time, token rate, generated token count, and total model-forward time.
Do not worry if the generated text is strange. GPT-2 is an older base model, not a chat- or instruction-tuned model, and this demo uses a simple sampling loop. The purpose is to inspect the runtime integration and timing behavior, not to build a production text-generation application.
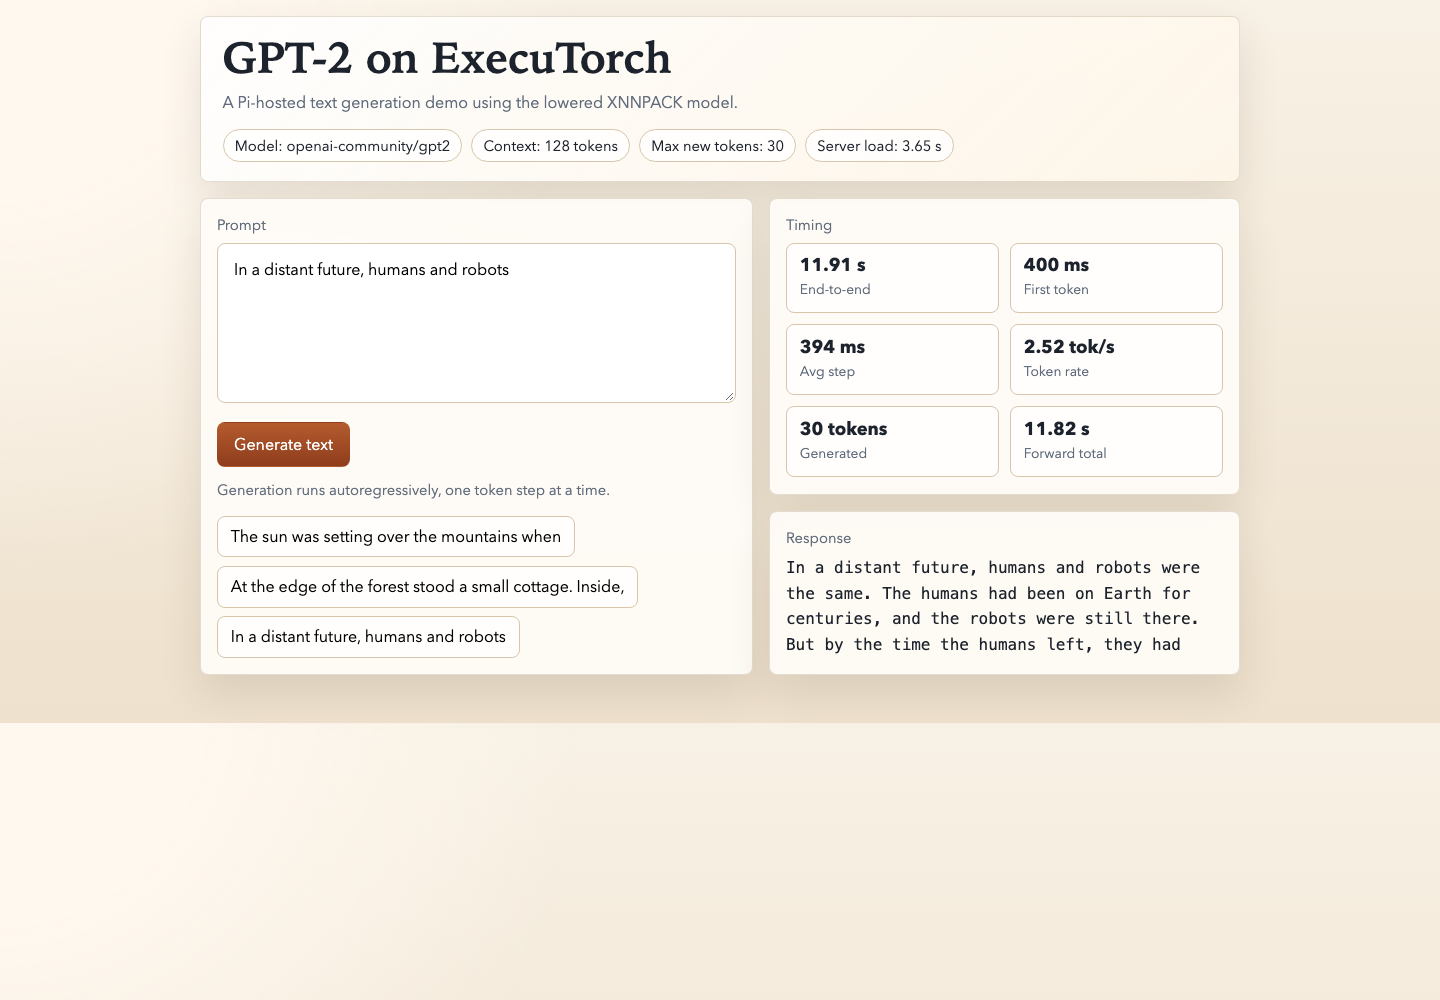
The demo takes longer than the benchmark because the benchmark measures one fixed next-token forward pass, while the demo generates many tokens. The demo does not use a KV cache, so each generated token runs another forward pass over the current context window. The total latency is the cost of many ExecuTorch forwards plus tokenization, sampling, and page handling.
You could implement a KV cache yourself, and production text-generation systems normally do. Instead of recomputing attention over the whole context on every step, the app stores the previous key/value tensors and feeds them back into the model for the next token. That is much faster for longer generations, but it also changes the model interface: the exported program needs cache inputs and cache outputs, the app has to manage cache tensor shapes and positions, and the benchmark needs to measure a different decode path. This is out of scope for this module, which focusses on understanding the ExecuTorch workflow.
Understand the code
The serving script is mostly HTTP server and page-handling code. The ExecuTorch-specific application logic is in module-1-transformer-inference-with-xnnpack/scripts/pi/core/gpt2_generation_core.py.
First, the app loads the tokenizer and the lowered .pte artifact:
from _support.common import load_executorch_program
from transformers import AutoTokenizer

tokenizer = AutoTokenizer.from_pretrained(spec["model_id"])
if tokenizer.pad_token is None:
    tokenizer.pad_token = tokenizer.eos_token
tokenizer.padding_side = "right"
model = load_executorch_program(pte_path)
Then, each generation step prepares the fixed-shape input expected by the exported model, calls ExecuTorch, samples a next token, and appends it to the running sequence:
in_ids = input_ids[:, -ctx:]
in_mask = attention_mask[:, -ctx:]
if in_ids.shape[1] < ctx:
    pad = ctx - in_ids.shape[1]
    pad_ids = torch.full((1, pad), tokenizer.pad_token_id, dtype=in_ids.dtype)
    in_ids = torch.cat([in_ids, pad_ids], dim=1)
    in_mask = torch.cat([in_mask, torch.zeros((1, pad), dtype=in_mask.dtype)], dim=1)

logits = self.model.forward((in_ids, in_mask))[0]
next_token = torch.multinomial(
    torch.softmax(logits / temperature, dim=-1),
    num_samples=1,
)

input_ids = torch.cat([input_ids, next_token], dim=1)
attention_mask = torch.cat([attention_mask, torch.ones_like(next_token)], dim=1)
A loaded ExecuTorch method can be invoked repeatedly. Here,
model.forward() runs once for each generated token, while the application
updates the token IDs and attention mask between calls. The .pte program
does not implement the generation loop; the application does.
In a production application, this surrounding code would often be written in C++ or integrated into a native mobile app rather than served from a small Python script. The important pattern is the same: the model is exported and lowered ahead of time, copied to the target as a .pte, loaded by the runtime, and called from application code. The application handles tokenization, input shaping, sampling, output decoding, and UI behavior.
Optional Next Steps
LLM-Specific Tooling
The GPT-2 exercise built a decoder model path by hand. That made the
pieces visible: torch.export, fixed-shape inputs, portable lowering,
XNNPACK delegation, fallback operators, and a simple generation loop.
Real LLM deployment usually needs more than the .pte artifact used in
the simple GPT-2 example. A packaged LLM path also has to account for:
- tokenizer files and vocabulary metadata
- beginning-of-sequence and end-of-sequence token IDs
- maximum sequence length
- KV cache inputs and outputs for faster token-by-token generation
- generation settings such as sampling and stopping behavior
- optional quantization choices for weights, embeddings, and linear layers
ExecuTorch provides LLM-focused tooling for this. The two main entry points to read about next are:
export_llm: ExecuTorch’s native LLM export API for optimized model families such as Llama, Qwen, Phi, and SmolLM2.- Optimum ExecuTorch
:
the Hugging Face-oriented path, including
optimum-cli export executorchand Python helpers for exported model packages.
For example, an Optimum ExecuTorch export command can select the model, task, backend recipe, KV cache behavior, quantization settings, and maximum sequence length.
This is an illustrative command. Optimum is not installed by the course requirements, and its command-line options can change. Follow the linked Optimum ExecuTorch documentation before trying it.
optimum-cli export executorch \
  --model "HuggingFaceTB/SmolLM2-135M-Instruct" \
  --task "text-generation" \
  --recipe "xnnpack" \
  --use_custom_sdpa \
  --use_custom_kv_cache \
  --qlinear 8da4w \
  --qembedding 8w \
  --max_seq_len 128 \
  --output_dir smollm2_optimum
The xnnpack recipe selects the optimized CPU backend,
--use_custom_kv_cache enables the cache path used during generation,
and the quantization flags show where size and latency trade-offs enter
the LLM export flow.
This module does not provide a full packaged LLM walkthrough. The setup has more moving parts than the GPT-2 and DistilBERT examples, and the result depends heavily on model size, cache support, quantization, and the target runtime. If you want to continue in that direction, start with the ExecuTorch working with LLMs documentation.
For a straightforward example of running another LLM using ExecuTorch, try the Arm Learning Path Run Llama3 on Raspberry Pi 5 using ExecuTorch .
Course complete
Nice work
You completed Optimize and deploy AI inference with ExecuTorch on Arm.